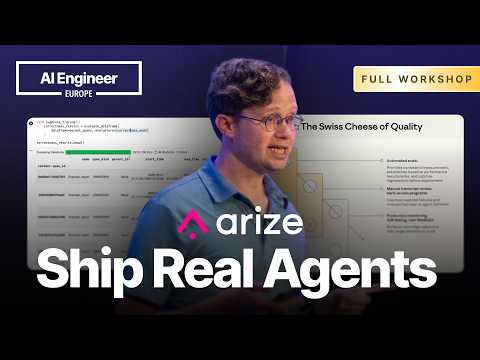
Khan explains how AI PM work has changed, from prototyping with AI tools to getting systems ready for production. He compares evals to software tests, while noting that agents are nondeterministic and depend on the data they use. He introduces an LLM-as-a-judge eval as a way to label outputs against a defined goal.
Shipping AI That Works: An Evaluation Framework for PMs
Speaker
Aman Khan, an AI product manager at Arize, leads an AI Engineer workshop on evaluating AI products and agents, with a live trip planner demo and audience Q&A.
Khan builds a trip planner with multiple agents for budgeting, local experiences, and research, which feed an itinerary agent. Traces show the agents’ inputs, outputs, and actions; a prompt playground lets the team inspect and change prompts. He argues PMs should understand the system and take part in prompt decisions because they own the product outcome.
Khan cautions that a single output cannot show whether a prompt change works at scale. He creates a dataset from 15 synthetic itineraries and compares two prompt versions across 12 examples. LLM-based evals check tone and whether the itinerary offers a discount, while human labels help assess whether those evals are accurate.
Khan says lowering an evaluator model’s temperature can reduce variance, though it cannot eliminate it. In the demo, the judge rates outputs as friendly even when human labels call them robotic, showing that evals need their own checks. He recommends comparing judge results with human labels, refining the eval prompt, and adding examples.
Khan presents eval datasets and criteria as a way to express product requirements and check whether a system is ready to ship. He describes iterating on curated examples during development, then using production data to find new difficult cases. In Q&A, he says the PM’s role includes owning the end experience and helping maintain useful data and evals with the team.
Takeaways
- Treat eval criteria and datasets as testable product requirements.
- Inspect agent traces to understand how inputs and outputs move through the system.
- Compare prompt versions across a dataset instead of judging a single response.
- Check LLM-as-a-judge results against human labels and improve mismatches.
- Keep sampling production data to find difficult cases and update the eval set.
Mentioned in this talk




Search inside this talk
What was claimed 17
- builtopen-source AI observability platform
“Phoenix is our lovely open-source project.”
5:16inFrom Vibes to Production: Evaluating and Shipping AI Agents That Work 101YouTube Verified13 sources· Talk, Job posting, Web· archived
- built
 Arize AI built OpenInference
“Arize was first to market with OpenInference in 2023.”
5:40inThe Transcript Looked Fine. The Call Wasn't.YouTube Verified3 sources· Talk, Web· archived
- previously atmachine learning platform and recommender systems
“After that, I went to Spotify to work on the machine learning platform and recommender systems.”
YouTube Verified3 sources· Talk, Web· archived
- previously atengineering; product manager for evaluation systems
“I started my career in engineering, working on self-driving cars at Cruise. While I was there, I became a PM for evaluation systems.”
YouTube Verified2 sources· Talk, Web· archived
- works atHead of Product
“I'm an AI product manager at a company called Arize.”
YouTube Verified2 sources· Talk, Web· archived
- builtAman Khan built AI trip planner
“I built this over the weekend.”
YouTube Unverified1 source· Talk
- featureArize AI: AI observability, evaluation, and development workflows on a unified platform
“We want to build a single, unified platform for you to run observability, evaluate, and ultimately develop these workflows.”
YouTube Unverified1 source· Talk
- featureArize AI: Visualizes agent systems as traces and spans
“We have this new agent visualization in the platform that shows the starting point, with multiple agents underneath it.”
YouTube Unverified1 source· Talk