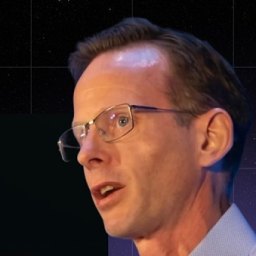
Kamradt describes intelligence using François Chollet’s definition: the ability to learn new things. ARC-AGI tests that ability with tasks that ordinary people can solve, rather than increasingly difficult questions aimed at expert-level knowledge. He contrasts this with AI systems that excel at specific skills such as chess or Go but may not transfer those skills to new problems.
How Intelligent Is AI, Really?
Speakers
Greg Kamradt, president of the ARC Prize Foundation, discusses how ARC-AGI benchmarks test generalization with Diana at a Y Combinator event in San Diego.
Kamradt recalls that GPT-4 without reasoning scored about 4% or 5% on ARC, while early tests of o1 reached about 21%. He says the jump helped show how much reasoning methods could change performance. Major labs including OpenAI and xAI have since reported ARC-AGI results, though he cautions that their adoption is secondary to the foundation’s goal of advancing open research.
Kamradt warns that reinforcement learning environments can produce strong benchmark scores without showing that a system can handle future problems. Since it is impractical to build an environment for every possible task, he argues that research should focus on systems that generalize without task-specific training. Hidden test sets help assess performance on problems the system has not seen.
Kamradt describes ARC-AGI-1 as a static benchmark of 800 tasks created by François Chollet, and ARC-AGI-2 as a deeper version released in March 2025. He says ARC-AGI-3 is planned as an interactive benchmark with about 150 game-like environments and no instructions: systems must act, observe responses, and infer the goal. Each environment will be checked with ordinary people, and those that do not meet a solvability threshold will be excluded.
Kamradt says intelligence evaluation should consider training data and energy as well as accuracy; wall-clock time can change with added compute. ARC-AGI-3 will compare how many actions AI systems and humans need to complete each environment, limiting brute-force play. He says a perfect ARC score would be strong evidence of generalization, but not sufficient to establish AGI.
Takeaways
- A high score on a narrow benchmark does not show that a model can transfer its skills to unfamiliar tasks.
- Use hidden tests to check whether systems can handle problems beyond their training environments.
- Evaluate efficiency alongside accuracy, including data needs, energy, and actions required.
- Test benchmark tasks with people to confirm they are solvable by ordinary humans.
- Treat a benchmark result as evidence about a capability, not as a complete definition of AGI.
Mentioned in this talk


Search inside this talk
What was claimed 13
- role atGreg Kamradt is president at
 ARC Prize Foundation
“Greg Kamradt, who is the president of the ARC Prize Foundation.”
YouTube Unverified1 source· Talk
- featureARC Prize Foundation: Mission: pull forward open progress toward systems that can generalize just like humans
“Our mission is to pull forward open progress toward systems that can generalize just like humans.”
YouTube Unverified1 source· Talk
- featureARC-AGI: Tests the ability to learn new things
“It tests your ability to learn new things.”
YouTube Unverified1 source· Talk
- metricGPT-4: about 4–5% as a base model with no reasoningabout 4–5% as a base model with no reasoning
“GPT-4, the base model with no reasoning, was getting 4% or 5%.”
YouTube Unverified1 source· Talk
- usesreports benchmark numbers as part of model releases
“xAI and OpenAI—are using ARC-AGI as part of their model releases and reporting their numbers.”
YouTube Unverified1 source· Talk
- usesreports benchmark numbers as part of model releases
“OpenAI—are using ARC-AGI as part of their model releases and reporting their numbers.”
YouTube Unverified1 source· Talk
- metric
 o1: performance reached about 21%performance reached about 21%
“I think performance jumped to 21%.”
YouTube Unverified1 source· Talk
- metricARC-AGI 3: About 150 interactive environments
“ARC-AGI-3 is going to have about 150 video game environments.”
YouTube Unverified1 source· Talk